Read this first. One case study, one artefact, no outside adopters. A model proposed the classification of all 99 provisions and two of the four authors checked it. Nobody outside that group has validated it yet. The paper's own limits section says what would fix that, and the PDF linked below has the full argument. This page has the shape of it.
The problem
CSRD makes every large company in Europe publish an audited account of what it does to people and the environment, and what sustainability issues do to its finances. Before any of that gets written, the company runs a double materiality assessment, which decides what goes in the report and what never appears at all. Get that step wrong and every downstream number answers the wrong question.
The standards governing it run to 99 obligations. They state a rule and decline to set the number: a company must apply a "materiality threshold" and is never told what the threshold should be. The job usually lands on whoever is free, with no background in the standard and no benchmark to check the result against. ESMA reviewed 91 issuers after the first reporting cycle. Only 61.7% met the objective for this step, some disclosures were boilerplate, and two issuers got a qualified opinion, one of them specifically for the materiality assessment. No AI was involved in any of it.
Vendors are already selling AI as the fix. We wanted to know which parts of the regulation it can actually reach.
Three kinds of provision
Every provision is a decision in one of three states. Already decided: the rule is fully stated and a machine executes it exactly, no judgement involved. Left open: the rule is stated and the number is not, so a person has to supply a value and the standard requires them to say why. Out of reach: the obligation needs judgement about the company's own circumstances that no model can supply, such as engaging a workforce or a supplier.
A model read all 99 provisions and proposed a category and a reason for each. An author checked every proposal against the text, and a second author independently reviewed all 99 rows and agreed the result. The model did the reading. The authors made the calls.
| Source | Already decided | Left open | Out of reach | Total |
|---|---|---|---|---|
| ESRS 1 | 18 | 4 | 15 | 37 |
| ESRS 2 | 8 | 1 | 22 | 31 |
| Nine topical standards | 0 | 12 | 19 | 31 |
| Total | 26 | 17 | 56 | 99 |
The left open group is the smallest and decides the most. Seventeen provisions, and two of them are the materiality determinations themselves. The topical standards contribute no already decided provisions at all, because every mechanical rule in them runs after the scope is already set.
What we built
Vera, the CSRD platform elsewhere on this site, is the artefact in the paper. It takes a company through the assessment as a nine step sequence and produces a workpaper an assurance provider can read. One of us, not a software engineer, built it in 124 commits over 83 days with AI assisted tooling, encoding the 26 already decided provisions as executable rules in most of 19 working days.
At runtime nothing calls a model. The scoring engine has no way to reach the internet, so it cannot call one even by accident. What it does instead is refuse. It will not let a topical standard be skipped, will not score a record without all six scores, and will not close an approval without a named submitter and approver. A complete assessment of 20 records across all ten topical standards ran end to end against the frozen build, with 506 unit tests and 13 integration tests passing. That is what it means to say the already decided group is genuinely decided.
What we found
A machine can enforce that a decision was made. It cannot enforce that the decision was any good. We found the gap between those two in our own build, in five places.
Every record carries a required field for where in the supply chain an impact sits, and another for the reason behind a materiality threshold. Both accept an empty string. Nothing in the code checks whether they hold anything, so a record with nothing in that field gets scored and exported to a client workpaper where it prints as "Not captured". No code path even lets anyone set a threshold yet, so every assessment ships with a default reason that says, in effect, somebody should write the reason. A non-empty check would have been trivial. What the standard actually needs is a named approver attached to the value, which is a process control, not a validation rule.
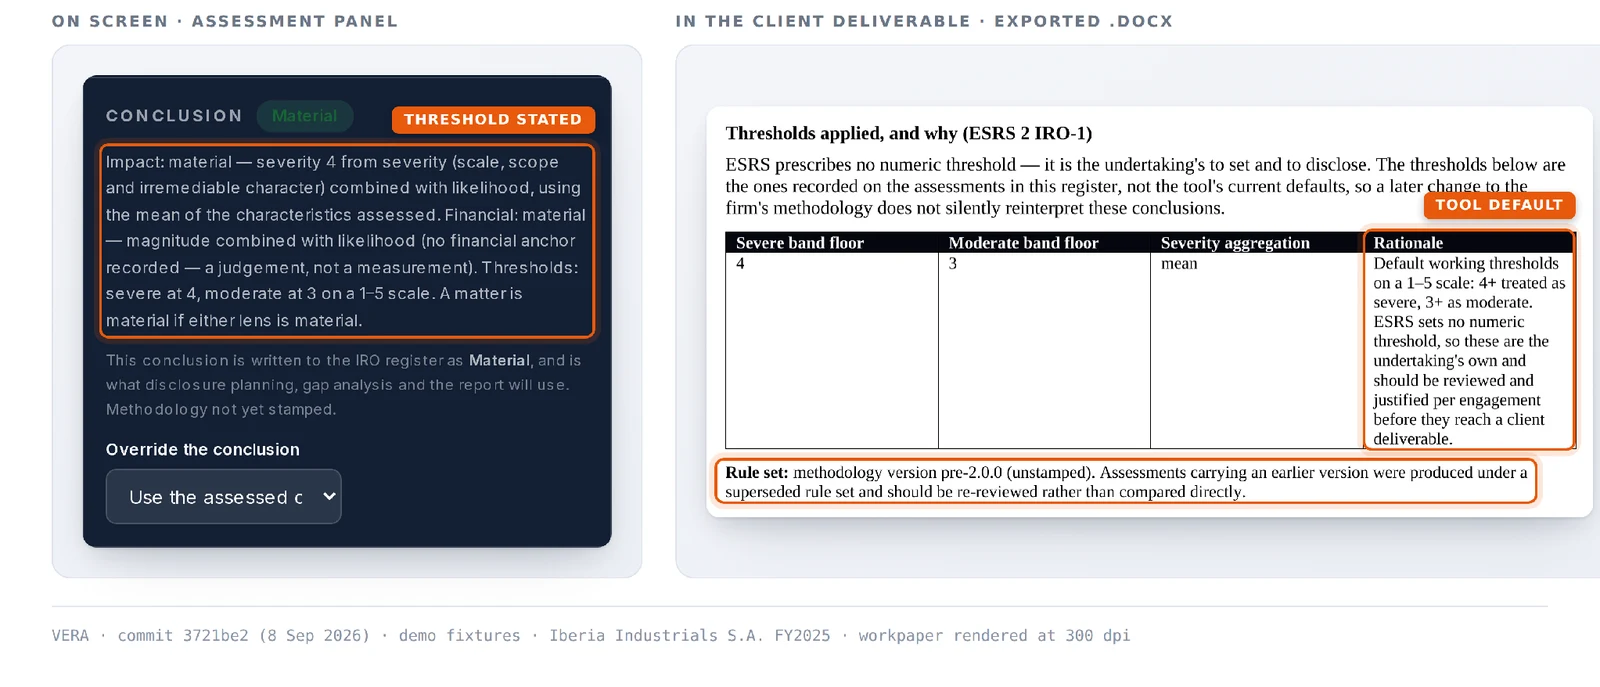
Autonomy makes the same failure worse by removing the author. In one development session an agent applied twelve database migrations with nobody watching. One caused infinite recursion in the read policies, and the service was down for two hours. Nobody had signed off on any of the twelve. That is the exact failure mode the classification predicts for the left open group, found by a team that was trying to be careful.
What it means
73 of the 99 provisions cannot be resolved by a machine at all, and no future model shrinks that number, because it belongs to how the regulation is written rather than to the state of the technology. The useful question about any compliance tool in this market is not whether it helps. It is which of the three states it operates on, and who signs for the rest.
The method is not specific to sustainability reporting. Tax rules set thresholds and leave "reasonable" undefined. Procurement sets a procedure and leaves "proportionate" open. Any regulation containing "shall" and an undefined term has the same three way split waiting to be mapped, and mapping it is cheap: reading the regulation is what AI did best here, and it needs no platform at all.